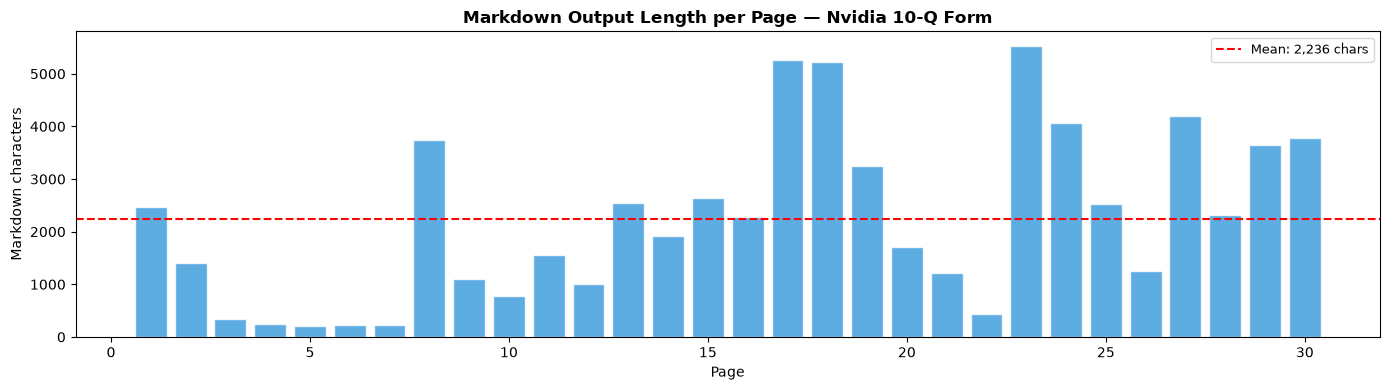
# ── 2d. Export full markdown to file ────────────────────────────────────────

full_md = '\n\n---\n\n'.join(
    f'<!-- Page {p["index"] + 1} -->\n{p.get("markdown", "")}'
    for p in pages
)

output_md_path = os.path.join(os.path.dirname(os.path.abspath('__file__')),
                               'nvidia_10q_ocr4_output.md')
with open(output_md_path, 'w', encoding='utf-8') as f:
    f.write(full_md)

print(f'Full markdown saved to: {output_md_path}')
print(f'File size             : {os.path.getsize(output_md_path):,} bytes')
Full markdown saved to: /Users/peymanmohajerian/Documents/tech/microsoft/cook-book/microsoft/ocr4-doc-ai/nvidia_10q_ocr4_output.md
File size             : 67,834 bytes
2e. Quinta opción: manejo de tablas en la página 6 con celdas vacías preservadas
Cuando las tablas de OCR contienen celdas en blanco, el riesgo principal es que un valor faltante desplace las columnas restantes hacia la izquierda. El enfoque más seguro es rellenar las filas cortas antes de construir un DataFrame para que los espacios en blanco permanezcan en su lugar y no corrompan el resultado.
Este ejemplo usa la tabla de la página 6 del informe 10-Q de Nvidia y muestra que las celdas vacías se tratan como valores faltantes, no como datos que mueven las columnas vecinas.
# ── 2e. Fifth table-handling option: page 6, empty cells preserved ────────
page6 = next((page for page in pages if page.get('index') == 5), pages[5])
page6_table_md = next(
    (
        (table.get('content') or '').strip()
        for table in page6.get('tables', [])
        if (table.get('content') or '').strip()
    ),
    '',
)

if page6_table_md:
    page6_df = markdown_table_to_df(page6_table_md)
    display(Markdown('### Page 6 — empty-cell-safe table parsing'))
    display(page6_df.head(10))
    print(f'\nParsed rows: {len(page6_df)}')
    print('Blank cells preserved as missing values:')
    print(page6_df.isna().sum().to_dict())
    print('\nColumns remain aligned after padding short rows:')
    display(page6_df.fillna('').astype(str).replace('nan', ''))
else:
    print('No table content was returned for page 6.')
<IPython.core.display.Markdown object>
Common Stock Outstanding  \
0               (In millions, except per share data)                   Shares
1                        Balances as of Jan 25, 2026                   24,304
2                                         Net income                        —
3                           Other comprehensive loss                        —
4                           Issuance of common stock                       37
5            Tax withholding related to common stock                     (12)
6                                 Shares repurchased                    (108)
7  Cash dividends declared and paid ($0.01 per co...                        —
8                           Stock-based compensation                        —
9                        Balances as of Apr 26, 2026                   24,221

          Additional Paid-in Capital Accumulated Other Comprehensive Income  \
0  Amount                       <NA>                                   <NA>
1    $ 24                   $ 10,118                                  $ 178
2       —                          —                                      —
3       —                          —                                   (41)
4       —                        515                                      —
5       —                    (2,129)                                      —
6       —                      (157)                                      —
7       —                          —                                      —
8       —                      1,928                                      —
9    $ 24                   $ 10,275                                  $ 137

  Retained Earnings Total Shareholders' Equity
0              <NA>                       <NA>
1         $ 146,973                  $ 157,293
2            58,321                     58,321
3                 —                       (41)
4                 —                        515
5                 —                    (2,129)
6          (20,013)                   (20,170)
7             (243)                      (243)
8                 —                      1,928
9         $ 185,038                  $ 195,474
Common Stock Outstanding
Additional Paid-in Capital
Accumulated Other Comprehensive Income
Retained Earnings
Total Shareholders' Equity
0
(In millions, except per share data)
Shares
Amount
<NA>
<NA>
<NA>
<NA>
1
Balances as of Jan 25, 2026
24,304
$ 24
$ 10,118
$ 178
$ 146,973
$ 157,293
2
Net income
—
—
—
—
58,321
58,321
3
Other comprehensive loss
—
—
—
(41)
—
(41)
4
Issuance of common stock
37
—
515
—
—
515
5
Tax withholding related to common stock
(12)
—
(2,129)
—
—
(2,129)
6
Shares repurchased
(108)
—
(157)
—
(20,013)
(20,170)
7
Cash dividends declared and paid ($0.01 per co...
—
—
—
—
(243)
(243)
8
Stock-based compensation
—
—
1,928
—
—
1,928
9
Balances as of Apr 26, 2026
24,221
$ 24
$ 10,275
$ 137
$ 185,038
$ 195,474
Parsed rows: 20
Blank cells preserved as missing values:
{'': 0, 'Common Stock Outstanding': 0, 'Additional Paid-in Capital': 1, 'Accumulated Other Comprehensive Income': 1, 'Retained Earnings': 1, "Total Shareholders' Equity": 1}

Columns remain aligned after padding short rows:
\
0                (In millions, except per share data)
1                         Balances as of Jan 25, 2026
2                                          Net income
3                            Other comprehensive loss
4                            Issuance of common stock
5             Tax withholding related to common stock
6                                  Shares repurchased
7   Cash dividends declared and paid ($0.01 per co...
8                            Stock-based compensation
9                         Balances as of Apr 26, 2026
10                        Balances as of Jan 26, 2025
11                                         Net income
12                         Other comprehensive income
13                           Issuance of common stock
14            Tax withholding related to common stock
15                                 Shares repurchased
16  Cash dividends declared and paid ($0.01 per co...
17  Fair value of partially vested equity awards a...
18                           Stock-based compensation
19                        Balances as of Apr 27, 2025

   Common Stock Outstanding         Additional Paid-in Capital  \
0                    Shares  Amount
1                    24,304    $ 24                   $ 10,118
2                         —       —                          —
3                         —       —                          —
4                        37       —                        515
5                      (12)       —                    (2,129)
6                     (108)       —                      (157)
7                         —       —                          —
8                         —       —                      1,928
9                    24,221    $ 24                   $ 10,275
10                   24,477    $ 24                   $ 11,237
11                        —       —                          —
12                        —       —                          —
13                       50       —                        370
14                     (13)       —                    (1,532)
15                    (126)       —                       (92)
16                        —       —                          —
17                        —       —                         22
18                        —       —                      1,470
19                   24,388    $ 24                   $ 11,475

   Accumulated Other Comprehensive Income Retained Earnings  \
0
1                                   $ 178         $ 146,973
2                                       —            58,321
3                                    (41)                 —
4                                       —                 —
5                                       —                 —
6                                       —          (20,013)
7                                       —             (243)
8                                       —                 —
9                                   $ 137         $ 185,038
10                                   $ 28          $ 68,038
11                                      —            18,775
12                                    158                 —
13                                      —                 —
14                                      —                 —
15                                      —          (14,411)
16                                      —             (244)
17                                      —                 —
18                                      —                 —
19                                  $ 186          $ 72,158

   Total Shareholders' Equity
0
1                   $ 157,293
2                      58,321
3                        (41)
4                         515
5                     (2,129)
6                    (20,170)
7                       (243)
8                       1,928
9                   $ 195,474
10                   $ 79,327
11                     18,775
12                        158
13                        370
14                    (1,532)
15                   (14,503)
16                      (244)
17                         22
18                      1,470
19                   $ 83,843
Common Stock Outstanding
Additional Paid-in Capital
Accumulated Other Comprehensive Income
Retained Earnings
Total Shareholders' Equity
0
(In millions, except per share data)
Shares
Amount
1
Balances as of Jan 25, 2026
24,304
$ 24
$ 10,118
$ 178
$ 146,973
$ 157,293
2
Net income
—
—
—
—
58,321
58,321
3
Other comprehensive loss
—
—
—
(41)
—
(41)
4
Issuance of common stock
37
—
515
—
—
515
5
Tax withholding related to common stock
(12)
—
(2,129)
—
—
(2,129)
6
Shares repurchased
(108)
—
(157)
—
(20,013)
(20,170)
7
Cash dividends declared and paid ($0.01 per co...
—
—
—
—
(243)
(243)
8
Stock-based compensation
—
—
1,928
—
—
1,928
9
Balances as of Apr 26, 2026
24,221
$ 24
$ 10,275
$ 137
$ 185,038
$ 195,474
10
Balances as of Jan 26, 2025
24,477
$ 24
$ 11,237
$ 28
$ 68,038
$ 79,327
11
Net income
—
—
—
—
18,775
18,775
12
Other comprehensive income
—
—
—
158
—
158
13
Issuance of common stock
50
—
370
—
—
370
14
Tax withholding related to common stock
(13)
—
(1,532)
—
—
(1,532)
15
Shares repurchased
(126)
—
(92)
—
(14,411)
(14,503)
16
Cash dividends declared and paid ($0.01 per co...
—
—
—
—
(244)
(244)
17
Fair value of partially vested equity awards a...
—
—
22
—
—
22
18
Stock-based compensation
—
—
1,470
—
—
1,470
19
Balances as of Apr 27, 2025
24,388
$ 24
$ 11,475
$ 186
$ 72,158
$ 83,843
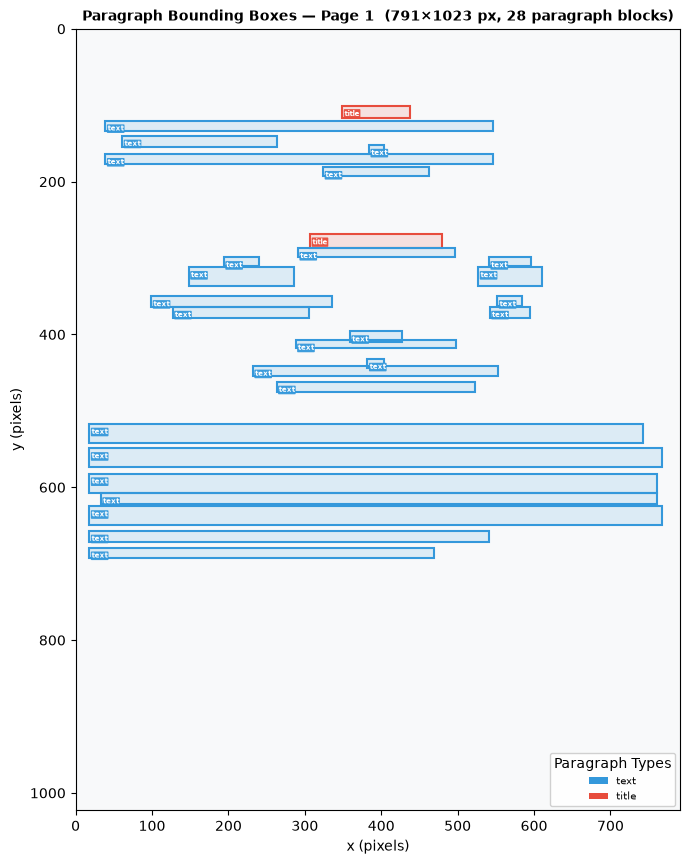
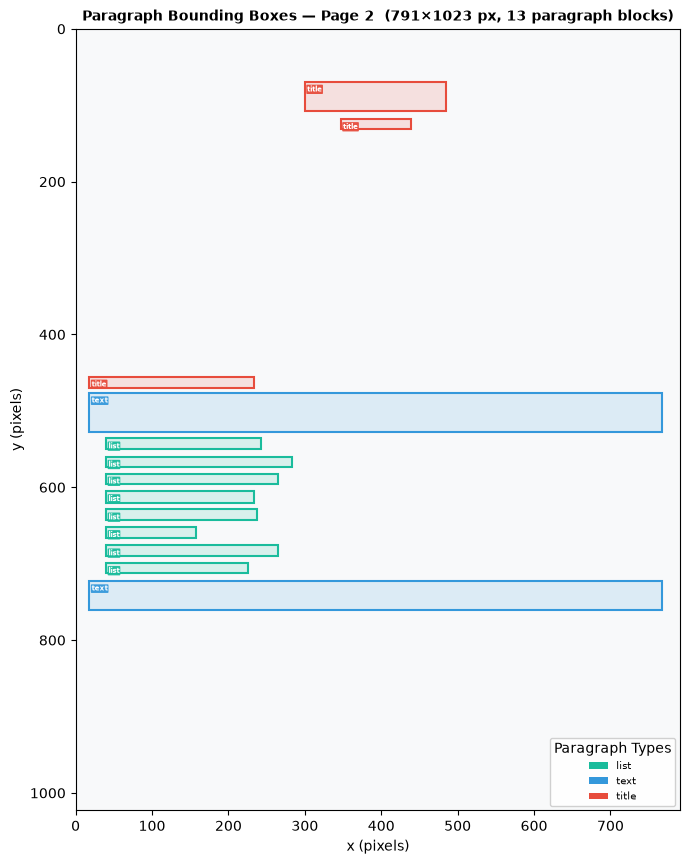
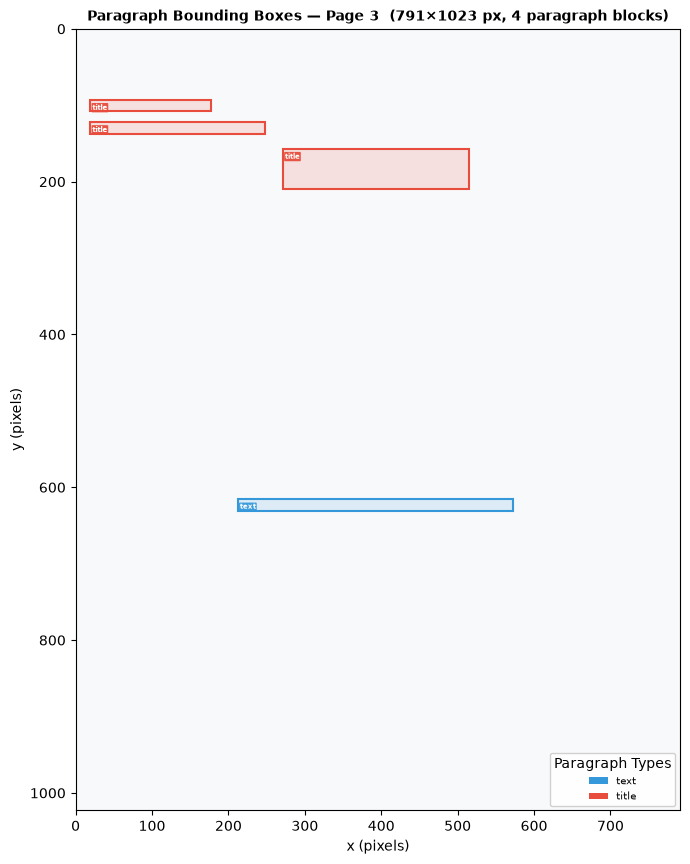
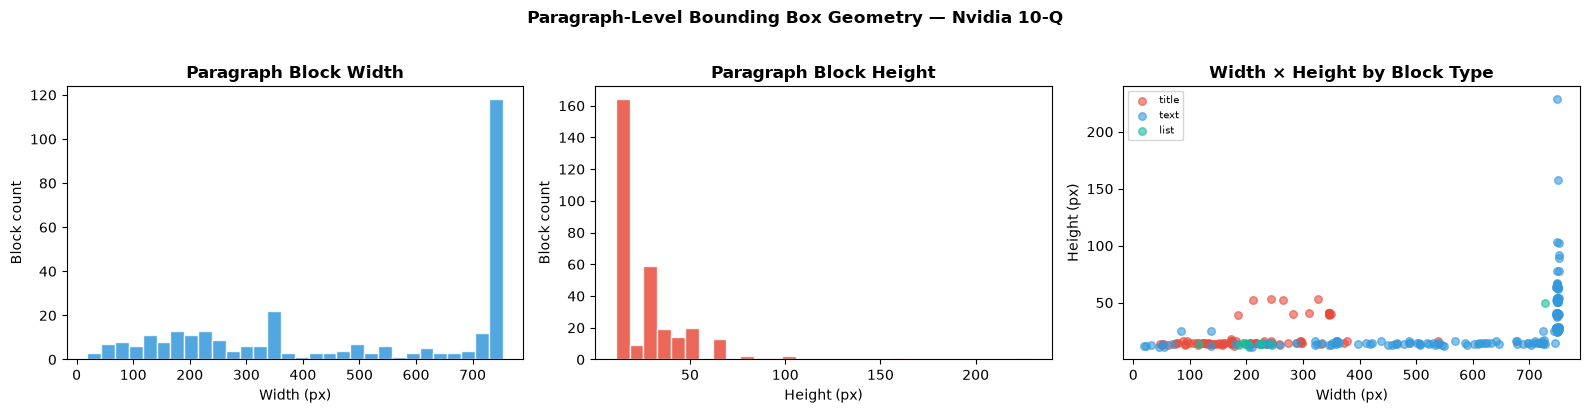
3. Cajas delimitadoras a nivel de párrafo
OCR-4 devuelve las coordenadas de píxeles para cada bloque detectado. Los bloques a nivel de párrafo incluyen: text, title, list, aside_text, caption, references.
Cada bloque de párrafo contiene:
top_left_x / top_left_y         (origin corner, pixels)
bottom_right_x / bottom_right_y (opposite corner, pixels)
type                             (semantic classification)
content                          (extracted text in markdown)
# ── 3a. Collect all paragraph-level blocks across the document ───────────────

para_rows = []
for p in pages:
    dims = p.get('dimensions') or {}
    for b in (p.get('blocks') or []):
        if b['type'] in PARAGRAPH_TYPES:
            w = b['bottom_right_x'] - b['top_left_x']
            h = b['bottom_right_y'] - b['top_left_y']
            para_rows.append({
                'page':        p['index'] + 1,
                'type':        b['type'],
                'x1':          b['top_left_x'],
                'y1':          b['top_left_y'],
                'x2':          b['bottom_right_x'],
                'y2':          b['bottom_right_y'],
                'width_px':    w,
                'height_px':   h,
                'area_px2':    w * h,
                'page_width':  dims.get('width', 0),
                'page_height': dims.get('height', 0),
                'content':     b['content'],
            })

df_para = pd.DataFrame(para_rows)
print(f'Total paragraph-level blocks : {len(df_para)}')
print(f'Across pages                 : {df_para["page"].nunique()} / {n_pages}')
print()
print(df_para['type'].value_counts().to_string())
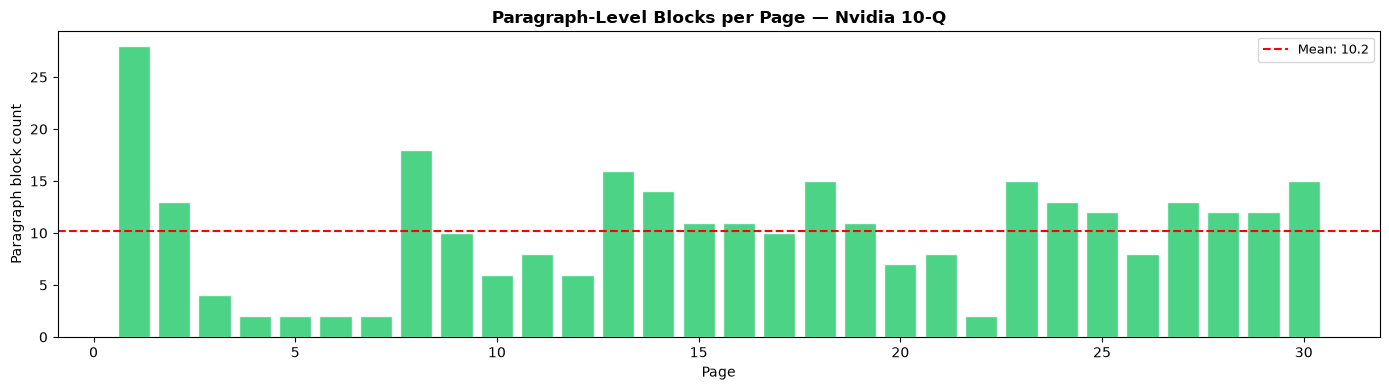
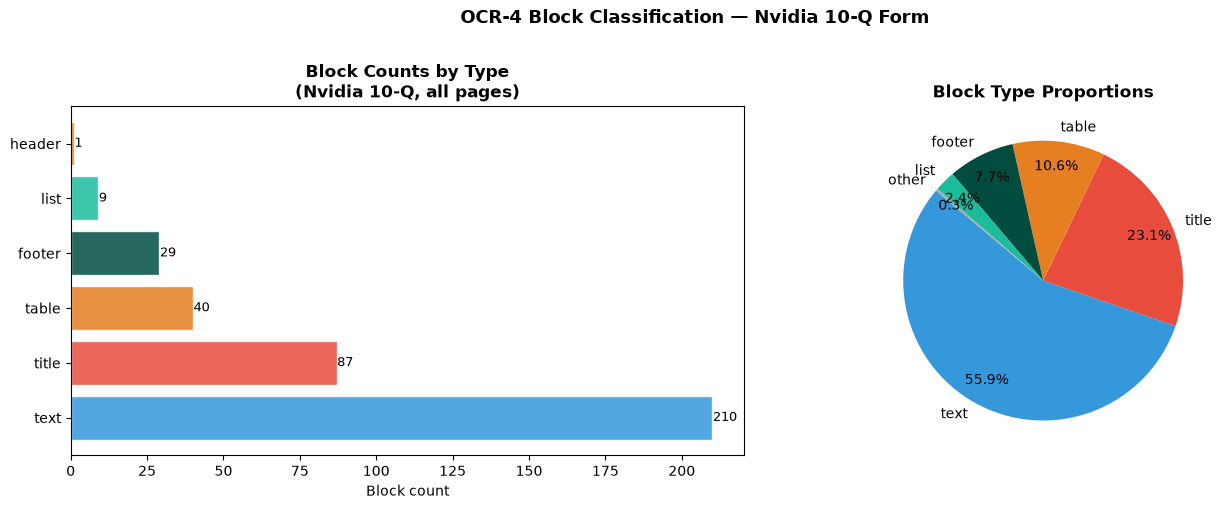
Total paragraph-level blocks : 306
Across pages                 : 30 / 30

type
text     210
title     87
list       9
Cada bloque se clasifica en uno de 13 tipos semánticos:
Categoría
Tipos
Estructura
title, header, footer
Párrafo
text, list, aside_text, caption, references
Especializado
table, image, equation, code, signature
La clasificación permite tareas posteriores como:
Extracción de tablas (filtrar bloques table)
Subtitulado de figuras (emparejar image con bloques caption adyacentes)
Eliminación de encabezados/pies de página para un texto limpio
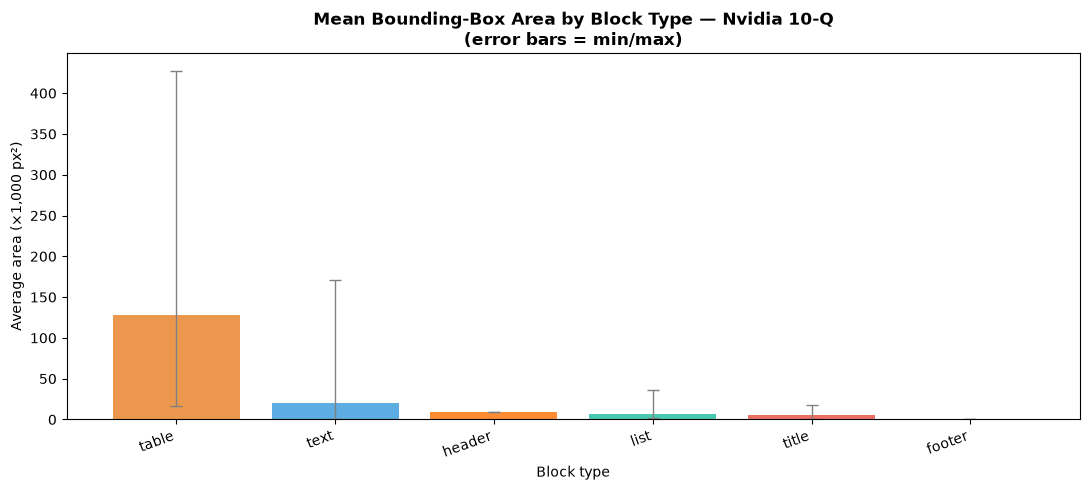
# ── 5a. Collect ALL blocks (all types) across every page ─────────────────────

all_rows = []
for p in pages:
    dims = p.get('dimensions') or {}
    for b in (p.get('blocks') or []):
        w = b['bottom_right_x'] - b['top_left_x']
        h = b['bottom_right_y'] - b['top_left_y']
        all_rows.append({
            'page':        p['index'] + 1,
            'type':        b['type'],
            'x1':          b['top_left_x'],
            'y1':          b['top_left_y'],
            'x2':          b['bottom_right_x'],
            'y2':          b['bottom_right_y'],
            'width_px':    w,
            'height_px':   h,
            'area_px2':    w * h,
            'content_len': len(b['content']),
        })

df_all = pd.DataFrame(all_rows)
print(f'Total blocks across {n_pages} pages: {len(df_all)}')
print()
print(df_all['type'].value_counts().to_string())
Total blocks across 30 pages: 376

type
text      210
title      87
table      40
footer     29
list        9
header      1
# ── 5b. Block-type distribution: bar + pie ────────────────────────────────────

type_counts = df_all['type'].value_counts()
colors      = [BLOCK_COLORS.get(t, '#888888') for t in type_counts.index]

fig, (ax_bar, ax_pie) = plt.subplots(1, 2, figsize=(14, 5))

# Bar chart
bars = ax_bar.barh(type_counts.index, type_counts.values,
                    color=colors, alpha=0.85, edgecolor='white')
for bar, val in zip(bars, type_counts.values):
    ax_bar.text(bar.get_width() + 0.2, bar.get_y() + bar.get_height() / 2,
                str(val), va='center', fontsize=9)
ax_bar.set_xlabel('Block count')
ax_bar.set_title('Block Counts by Type\n(Nvidia 10-Q, all pages)', fontweight='bold')

# Pie chart
threshold = 0.02 * type_counts.sum()
major     = type_counts[type_counts >= threshold].copy()
minor_sum = int(type_counts[type_counts < threshold].sum())
if minor_sum > 0:
    major = pd.concat([major, pd.Series([minor_sum], index=['other'])])
pie_labels = list(major.index)
pie_colors = [BLOCK_COLORS.get(lbl, '#AAAAAA') for lbl in pie_labels]
ax_pie.pie(major.values, labels=pie_labels, colors=pie_colors,
           autopct='%1.1f%%', startangle=140, pctdistance=0.82)
ax_pie.set_title('Block Type Proportions', fontweight='bold')

plt.suptitle('OCR-4 Block Classification — Nvidia 10-Q Form',
             fontsize=13, fontweight='bold', y=1.01)
plt.tight_layout()
plt.show()
<Figure size 1400x500 with 2 Axes>
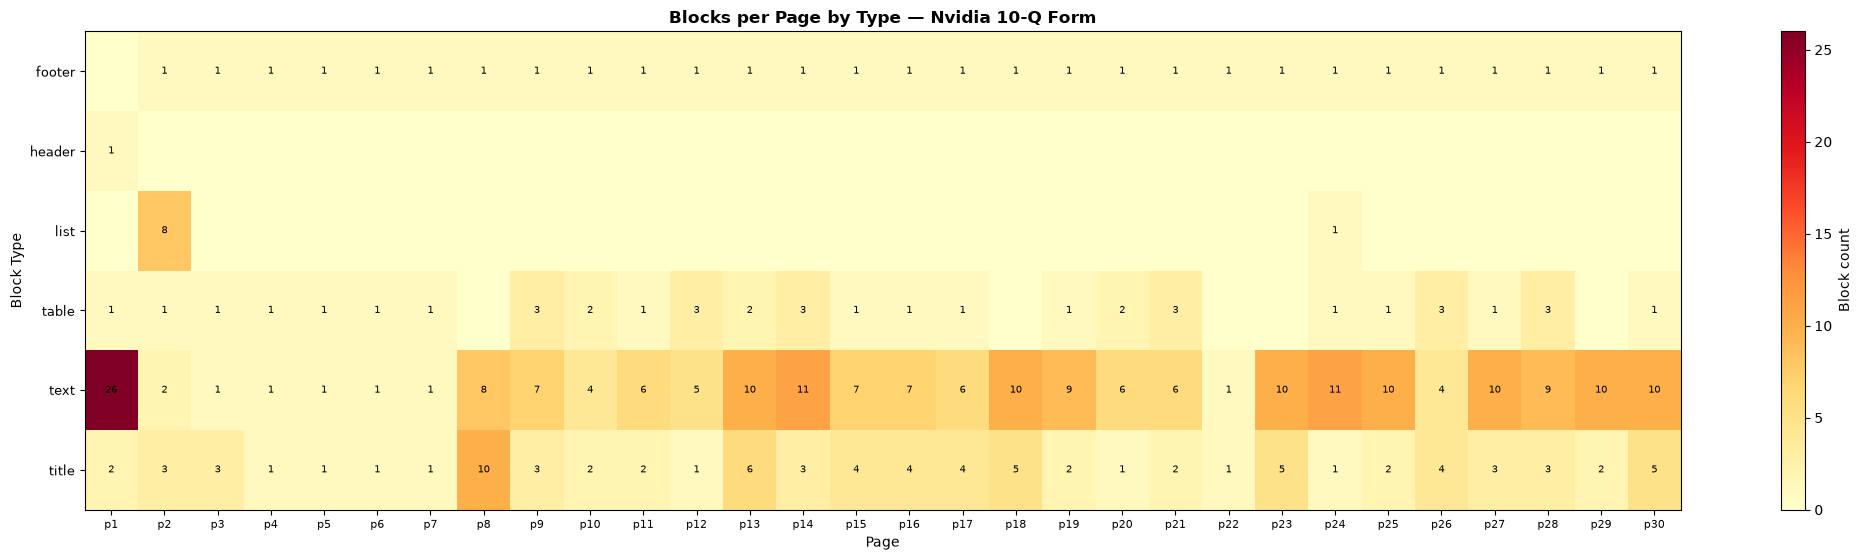
# ── 5c. Block-type heat-map: type × page ─────────────────────────────────────

pivot = (
    df_all.groupby(['type', 'page'])
    .size()
    .unstack(fill_value=0)
    .reindex(columns=range(1, n_pages + 1), fill_value=0)
)

fig, ax = plt.subplots(figsize=(max(10, n_pages * 0.7), len(pivot) * 0.7 + 1.5))
im = ax.imshow(pivot.values, aspect='auto', cmap='YlOrRd')

ax.set_xticks(range(n_pages))
ax.set_xticklabels([f'p{i}' for i in range(1, n_pages + 1)], fontsize=8)
ax.set_yticks(range(len(pivot.index)))
ax.set_yticklabels(pivot.index, fontsize=9)
ax.set_xlabel('Page')
ax.set_ylabel('Block Type')
ax.set_title('Blocks per Page by Type — Nvidia 10-Q Form', fontsize=12, fontweight='bold')

for i in range(len(pivot.index)):
    for j in range(n_pages):
        val = pivot.values[i, j]
        if val > 0:
            ax.text(j, i, str(val), ha='center', va='center',
                    fontsize=7, color='black')

plt.colorbar(im, ax=ax, label='Block count')
plt.tight_layout()
plt.show()
<Figure size 2100x570 with 2 Axes>
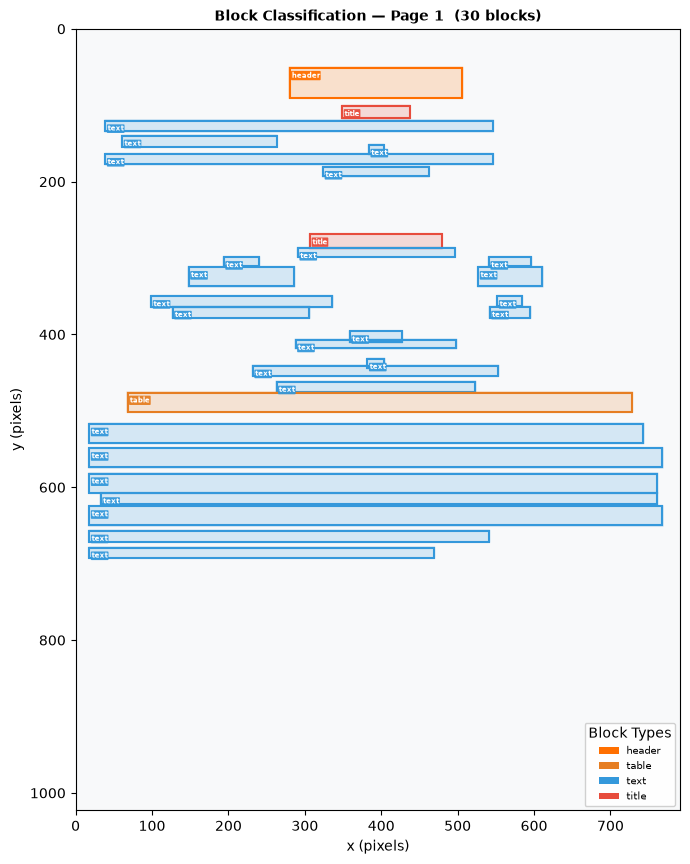
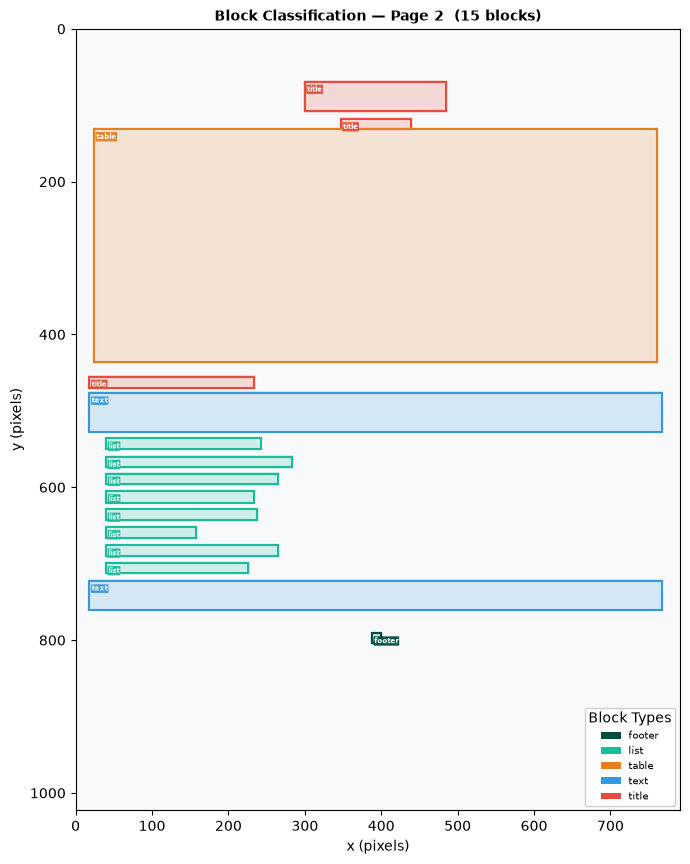
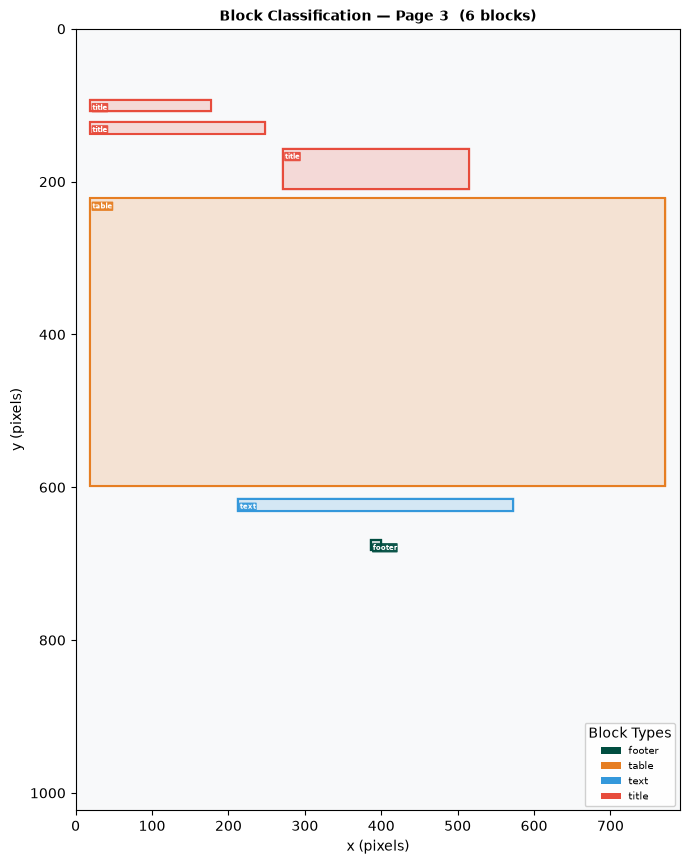
# ── 5d. Full block classification overlay on first three pages ───────────────

def render_all_blocks(page_data: dict, title: str = '') -> None:
    """Render ALL block types (including tables, images, headers) on one canvas."""
    dims   = page_data.get('dimensions') or {}
    width  = dims.get('width',  612)
    height = dims.get('height', 792)
    blocks = page_data.get('blocks') or []

    fig, ax = plt.subplots(figsize=(7, 10))
    ax.set_xlim(0, width)
    ax.set_ylim(height, 0)
    ax.set_facecolor('#F8F9FA')
    ax.set_aspect('equal')

    seen_types = set()
    for b in blocks:
        x1, y1 = b['top_left_x'], b['top_left_y']
        x2, y2 = b['bottom_right_x'], b['bottom_right_y']
        btype  = b['type']
        color  = BLOCK_COLORS.get(btype, '#888888')
        w, h   = x2 - x1, y2 - y1

        ax.add_patch(patches.FancyBboxPatch(
            (x1, y1), w, h,
            boxstyle='round,pad=2',
            linewidth=0, facecolor=color, alpha=0.18,
        ))
        ax.add_patch(patches.Rectangle(
            (x1, y1), w, h,
            linewidth=1.5, edgecolor=color, facecolor='none'
        ))
        ax.text(
            x1 + 3, y1 + 13, btype,
            fontsize=5, color='white', fontweight='bold',
            bbox=dict(boxstyle='round,pad=0.12', facecolor=color,
                      alpha=0.95, edgecolor='none'),
        )
        seen_types.add(btype)

    legend_handles = [
        patches.Patch(facecolor=BLOCK_COLORS.get(t, '#888'), label=t)
        for t in sorted(seen_types)
    ]
    ax.legend(handles=legend_handles, loc='lower right',
              fontsize=7, framealpha=0.9, title='Block Types')
    ax.set_title(title, fontsize=10, fontweight='bold')
    ax.set_xlabel('x (pixels)')
    ax.set_ylabel('y (pixels)')
    plt.tight_layout()
    plt.show()


for page_obj in pages[:3]:
    pg_num = page_obj['index'] + 1
    n_blk  = len(page_obj.get('blocks') or [])
    render_all_blocks(
        page_obj,
        title=f'Block Classification — Page {pg_num}  ({n_blk} blocks)',
    )
<Figure size 700x1000 with 1 Axes>
<Figure size 700x1000 with 1 Axes>
<Figure size 700x1000 with 1 Axes>
# ── 5e. One example per detected block type ──────────────────────────────────

print('Block Classification Examples — Nvidia 10-Q')
print('=' * 72)
for btype in df_all['type'].unique():
    row     = df_all[df_all['type'] == btype].iloc[0]
    # look up raw content from pages
    page_blocks = pages[row['page'] - 1].get('blocks') or []
    match = next(
        (b for b in page_blocks
         if b['type'] == btype
         and b['top_left_x'] == row['x1']
         and b['top_left_y'] == row['y1']),
        None
    )
    content = match['content'][:120].replace('\n', ' ') if match else '(n/a)'
    count   = (df_all['type'] == btype).sum()
    print(f'\n  TYPE : {btype.upper():12s}  ({count} across doc)')
    print(f'  PAGE : {row["page"]}')
    print(f'  BBOX : ({row["x1"]}, {row["y1"]}) → ({row["x2"]}, {row["y2"]})  '
          f'[{row["width_px"]}×{row["height_px"]}px]')
    print(f'  TEXT : {content}{"…" if len(content) == 120 else ""}')
    print('-' * 72)
Block Classification Examples — Nvidia 10-Q
========================================================================

  TYPE : HEADER        (1 across doc)
  PAGE : 1
  BBOX : (280, 51) → (506, 90)  [226×39px]
  TEXT : UNITED STATES SECURITIES AND EXCHANGE COMMISSION Washington, D.C. 20549
------------------------------------------------------------------------

  TYPE : TITLE         (87 across doc)
  PAGE : 1
  BBOX : (349, 101) → (437, 117)  [88×16px]
  TEXT : # FORM 10-Q
------------------------------------------------------------------------

  TYPE : TEXT          (210 across doc)
  PAGE : 1
  BBOX : (39, 120) → (546, 134)  [507×14px]
  TEXT : ☒ QUARTERLY REPORT PURSUANT TO SECTION 13 OR 15(d) OF THE SECURITIES EXCHANGE ACT OF 1934
------------------------------------------------------------------------

  TYPE : TABLE         (40 across doc)
  PAGE : 1
  BBOX : (68, 476) → (728, 501)  [660×25px]
  TEXT : |  Title of each class | Trading Symbol(s) | Name of each exchange on which registered  | | --- | --- | --- | |  Common …
------------------------------------------------------------------------

  TYPE : LIST          (9 across doc)
  PAGE : 2
  BBOX : (40, 536) → (242, 550)  [202×14px]
  TEXT : NVIDIA Corporate Blog (blogs.nvidia.com/)
------------------------------------------------------------------------

  TYPE : FOOTER        (29 across doc)
  PAGE : 2
  BBOX : (388, 791) → (400, 804)  [12×13px]
  TEXT : 2
------------------------------------------------------------------------
# ── 6. Final summary dashboard ────────────────────────────────────────────────

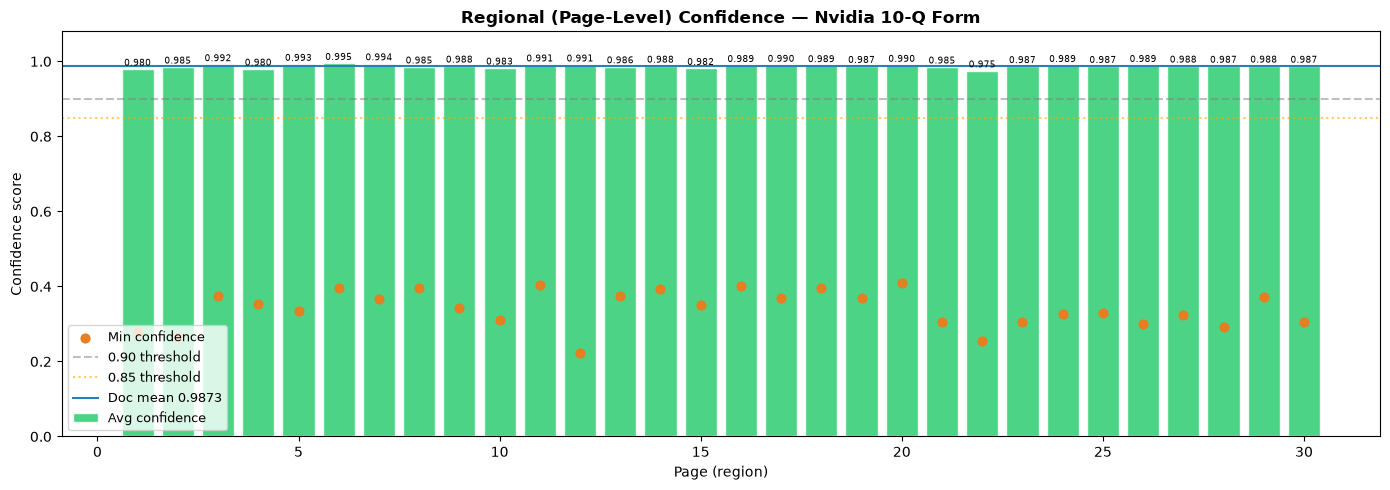
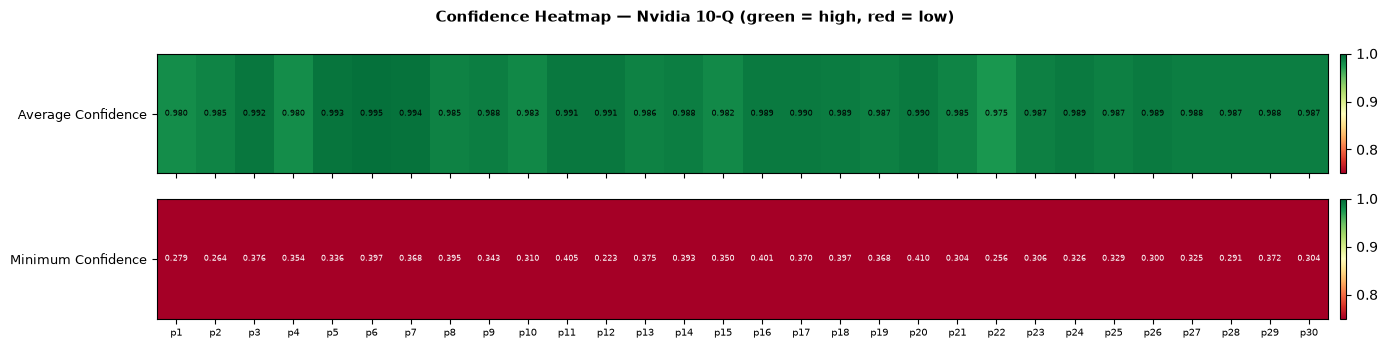
avg_conf    = valid['avg'].mean() if len(valid) else float('nan')
min_conf    = valid['minimum'].min() if len(valid) else float('nan')
n_para_blk  = len(df_para)
n_all_blk   = len(df_all)
types_found = sorted(df_all['type'].unique())

summary_md = f"""
### OCR-4 Results — Nvidia 10-Q Form

| Metric | Value |
|--------|-------|
| Pages processed | {n_pages} |
| Total markdown chars | {df_md['Chars'].sum():,} |
| Paragraph-level blocks | {n_para_blk} ({', '.join(sorted(PARAGRAPH_TYPES & set(types_found)))}) |
| All block types detected | {len(types_found)}: {', '.join(f'`{t}`' for t in types_found)} |
| Total blocks (all types) | {n_all_blk} |
| Doc avg confidence | {avg_conf:.4f} |
| Doc min confidence | {min_conf:.4f} |
| Pages ≥ 0.90 confidence | {(valid['avg'] >= 0.90).sum()} / {len(valid)} |
"""

display(Markdown(summary_md))
<IPython.core.display.Markdown object>
Lección del curso «Mistral Cookbook» de Mistral AI, publicado con licencia MIT. Traducción y adaptación al español de IA con Clase. IA con Clase no está afiliado a Mistral AI. Ver el original · Licencia
Esta lección es gratuita. El resto del curso se abre con la Membresía de IA con Clase, que incluye todos los cursos del catálogo. Ver precios